Key takeaways
- AI Overviews now show up on roughly half of Google searches, and ChatGPT alone handles hundreds of millions of weekly queries, so brand monitoring can no longer stop at rank tracking.
- The four metrics that matter are presence, citation rate, share of voice relative to named competitors, and sentiment. Position and content-type also matter, but only once the first four are in place.
- Citation behavior changes fast and unevenly by platform. Reddit's share of ChatGPT citations fell from roughly 3.8% to under 1% in a single week in August 2026, while Google's AI surfaces barely moved. A monitoring setup built for one engine will miss shifts on the others.
- Track non-branded, category-level prompts, not just your brand name. That's where AI actually introduces new customers to you, or to a competitor instead.
- Tools like Promptwatch can automate this tracking across every major AI engine and turn the findings into content actions, rather than leaving you with a dashboard nobody acts on.
Why this is a different problem than SEO tracking
For twenty years, "visibility" meant a position on a results page. You could screenshot it. You could rank-track it weekly and trust the number. AI search broke that model quietly, then all at once.
When someone asks ChatGPT "what's the best project management tool for a 10-person agency," there's no results page. There's an answer, generated on the fly, drawing on a handful of sources the model decided were worth citing (or not citing at all — plenty of AI answers name brands with zero link back). Google AI Overviews now appear on close to half of all US searches, up from roughly 6.5% in January 2025. That's not an incremental shift, it's a different discovery layer sitting on top of the one you've been optimizing for.
Here's the part that should worry any team still relying only on Semrush or Ahrefs rank data: research from Digital Applied found that only 38% of pages cited in AI Overviews also rank in the top 10 for the same query. You can be #1 on Google and completely absent from the AI answer for the exact same question. Ranking and being cited are correlated, but they are not the same thing, and tracking one tells you very little about the other.
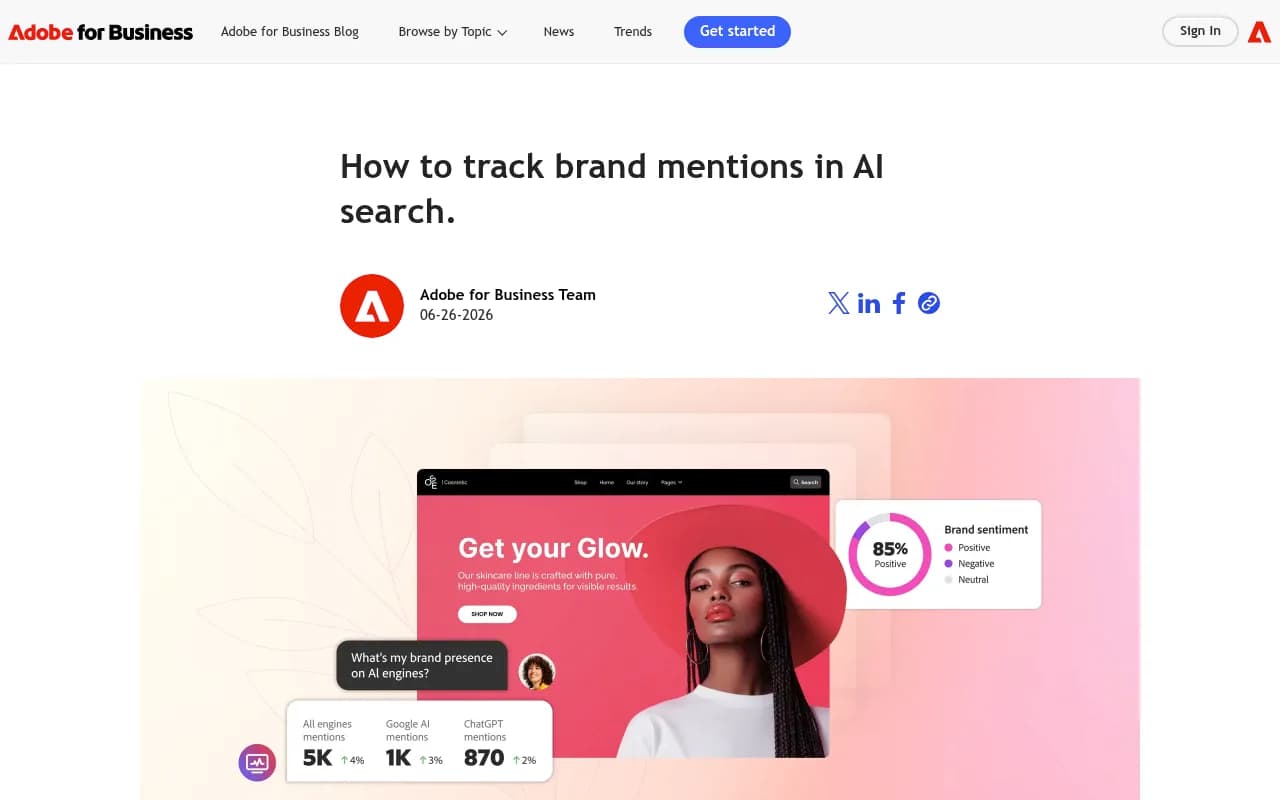
The four metrics that actually matter
Most brand-in-AI reporting drowns in vanity numbers. Strip it back to four things, in this order of importance.
Presence. Does your brand show up in the answer at all, for a given prompt, on a given day? This is binary and it's the foundation everything else sits on.
Citation rate. When your brand is mentioned, is there an actual source citation pointing to your domain, or is it just a name-drop with nothing backing it up? A citation with a link is worth far more than a mention with none, because it's the difference between an AI answer sending traffic and an AI answer simply borrowing your reputation.
Share of voice. This is where a lot of teams get fooled. You can have 40% visibility (your brand appears in 40% of tracked responses) but only 25% share of voice, because a competitor gets mentioned more often within those same answers. Visibility without competitive context is a half-story.
Sentiment. Is the AI's framing favorable, neutral, or negative? A brand that's cited constantly but described as "budget" or "basic" every time has a different problem than a brand that's simply invisible.
Position (where you rank within a list-style answer) and content type (is it your product page, a listicle, or a comparison piece getting cited) are worth tracking too, but they're diagnostic layers on top of the four above, not replacements for them.
Coverage: which platforms, and how they actually behave
A framework built only around ChatGPT will miss most of the picture. At minimum, track ChatGPT, Perplexity, Gemini, Google AI Overviews, Google AI Mode, Microsoft Copilot, and Grok. Each behaves differently enough that treating them as one "AI search" bucket produces bad conclusions.
Source volume alone varies wildly. Promptwatch's citation data shows ChatGPT typically cites around 5 sources per web-search-enabled response, Google AI Overviews cites roughly double that at close to 10, Perplexity is remarkably consistent at almost exactly 10 sources per answer day after day, and Microsoft Copilot swings from under 2 to nearly 17 sources per response, the least predictable of the four (Promptwatch's average sources per response data). If you're only counting "was I mentioned," you're ignoring the fact that getting one of 2 slots on Copilot is a very different achievement than getting one of 10 on Perplexity.
Platform behavior also changes underneath you without warning. After the GPT-5.3 rollout on March 4, 2026, ChatGPT's average citations per response dropped about 27%, from roughly 6.4 sources the week before to 4.7-4.9 by late March, and it never bounced back a month later. The drop hit every ChatGPT model simultaneously, which confirms it was a platform-level behavior change, not a fluke in one model (Promptwatch's citation drop analysis). If your monitoring only checks in monthly, you'd have missed the exact moment it happened and spent weeks debugging your own content instead.
Then there's the August 8, 2026 change: ChatGPT Search started using the site: operator at scale, jumping from roughly 0.4% to 17% of all fanout queries almost overnight. That means ChatGPT is now actively searching specific domains directly rather than relying purely on general web search, which makes your own site's internal search, crawlability, and indexation newly relevant to whether you get cited at all (Promptwatch's site: operator fanout report).
The Reddit cliff: a case study in why weekly tracking beats monthly
If you want one example of why cadence matters more than most teams assume, look at what happened to Reddit's share of ChatGPT citations in August 2026. Reddit held a steady ~3.8% share of ChatGPT Search citations from mid-July through the first week of August, then collapsed to an average of 0.52% between August 14 and 17, an 86% relative drop that never recovered (Promptwatch's Reddit citation data).
Here's the interesting part: Google's AI surfaces barely noticed. AI Overviews' Reddit share slid gradually from about 2.37% to 2.10% over the same window, and AI Mode dropped from 2.22% to 1.54%. No cliff, just a slow decline. Any brand whose GEO strategy was built entirely around "get cited on Reddit" just watched a huge chunk of its ChatGPT visibility evaporate in a week, while its Google AI visibility held roughly steady. This isn't the first time it's happened either — an earlier Promptwatch analysis of top ChatGPT citation sources found Reddit went from 10-14% of all ChatGPT citations to about 1% within days back in September 2025, after Reddit changed its own data-licensing terms.
The lesson isn't "avoid Reddit." It's that single-platform GEO strategies are fragile, and monthly audits will show you the aftermath weeks after it mattered. Weekly tracking of your critical prompt set is the minimum cadence that catches this kind of shift while there's still time to react.
A step-by-step monitoring framework
Step 1: build your prompt set, weighted toward non-branded queries
The single most common mistake in AI brand monitoring is testing only your brand name. "Is [Brand] good" tells you almost nothing about discovery. The prompts that matter are the ones a buyer types before they know your name: "best CRM for a 10-person agency," "how do I fix crawl errors on a Next.js site," "[Competitor] vs alternatives." Aim for a mix, roughly 20% branded, 50% category/problem-based, 30% comparison-style ("X vs Y" and "best X for Y").
Step 2: run the same set across every platform, on a fixed schedule
Weekly at minimum for your top 20-30 prompts, more often if you're in a fast-moving category. Because AI answers vary run-to-run even when nothing has changed on either side, a single snapshot isn't data. A tip worth stealing from practitioner discussion online: run the identical prompt set twice in the same week without changing anything, just to see how much natural variance exists before you attribute any real change to your own actions.
Step 3: log citation source, not just mention presence
For every response where you're mentioned, record whether there's a linked citation, which page it points to, and what content type that page is (product page, comparison, how-to, listicle). Content-type matters because the mix keeps shifting. In July 2026, ChatGPT's citation mix was roughly a third product pages, with listicles the fastest-growing format that month (Promptwatch's citation types data). If you're only writing comparison articles while the platform is increasingly citing product pages, you're optimizing for last quarter's behavior.
Step 4: score sentiment and competitive context, not just counts
Raw mention counts are a vanity metric on their own. Score whether the framing is favorable, and log which competitors show up alongside you on the same prompts. A brand mentioned in 60% of responses but always third, after two competitors named first, has a positioning problem that a "visibility" number alone hides.
Step 5: check your crawler logs, not just the AI answers
Citing behavior on the front end is downstream of crawling behavior on the back end. AI crawler traffic composition has changed a lot in 2026: OpenAI's crawlers went from roughly 95% of verified AI crawler requests in early June down to about 80% by early September, and Meta's WebIndexer crawler went from about 2% to nearly 38% of tracked AI crawler traffic between mid-July and early August (Promptwatch's Meta WebIndexer report). If your robots.txt, CDN rules, or WAF are still tuned only for GPTBot, you may be silently blocking crawlers that now matter.
Step 6: route findings to the people who can act on them, then re-measure
Tracking without a feedback loop into content and PR is just reporting. Send weekly deltas to content, product, and leadership, prioritize gaps by search volume and business relevance, and re-run the same prompt set after any content change to confirm it moved the needle, rather than assuming it did.
Common mistakes to avoid
- Tracking only branded queries and missing the non-branded discovery moments where AI actually introduces buyers to you or a competitor
- Auditing monthly, which misses fast platform shifts like the Reddit cliff or the site: operator rollout described above
- Treating all citations as equal, when a first-position linked citation is worth far more than a fifth-position unlinked mention
- Reporting a single snapshot number ("40% citation rate") without historical trend, so nobody can tell if it's improving or collapsing
- Watching only ChatGPT while ignoring Perplexity, Gemini, AI Mode, and Copilot, each of which has a distinct citation diet
- Confusing AI-citation visibility with real consumer sentiment; these are related but separate signals that need separate measurement
Comparing the tools built for this
The monitoring-tool category exploded in 2025-2026, and the players range from basic prompt trackers to full platforms that close the loop from insight to published content. Here's how the landscape breaks down.
| Tool | Platforms tracked | Crawler log analysis | Content generation/action layer | Starting price |
|---|---|---|---|---|
| Promptwatch | ChatGPT, Gemini, Claude, Perplexity, Grok, DeepSeek, Copilot, AI Overviews, AI Mode + more | Yes, 400+ crawlers, citation-rate per page | Yes, Content Agents publish to CMS, Unified Actions | $95/mo |
| Profound | 10+ platforms | Frontend monitoring only | Agents feature (newer, read/write) | ~$99/mo (Starter, ChatGPT only) |
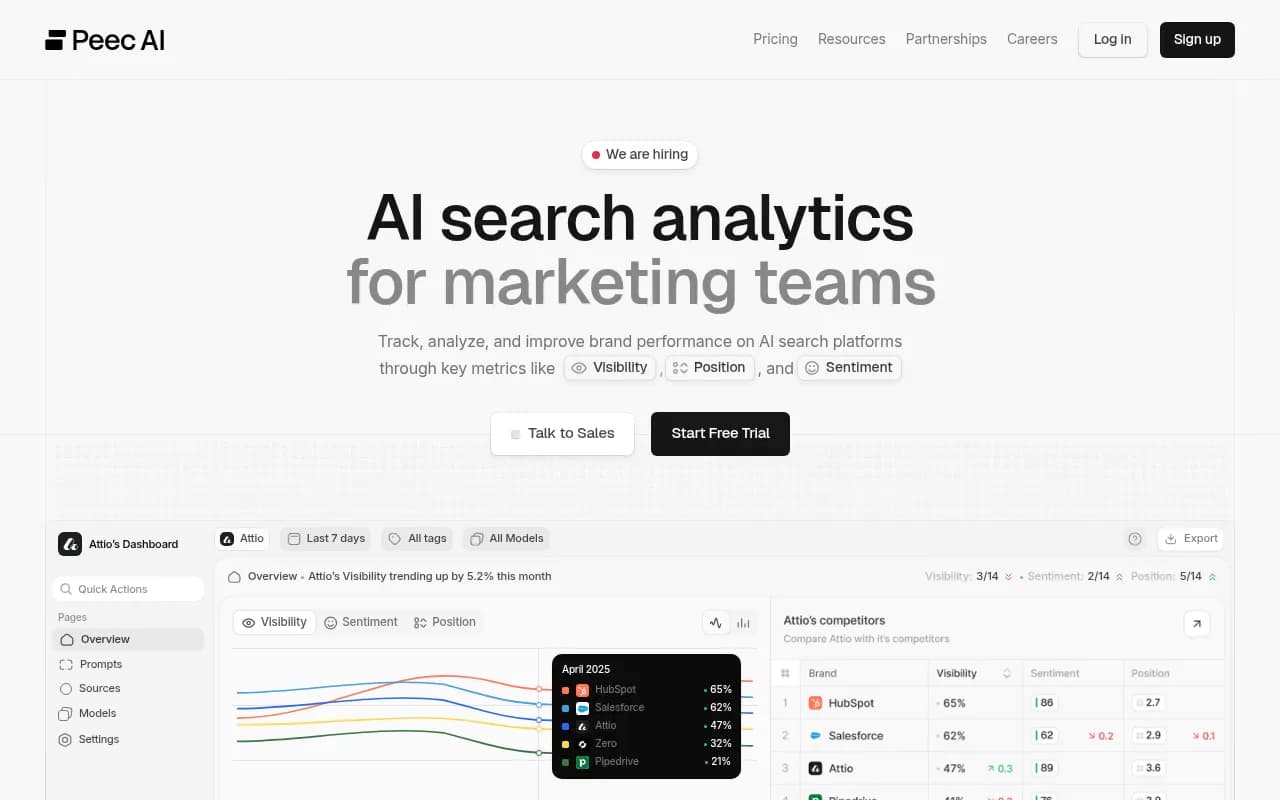
| Peec AI | Multi-platform, IP-based localization | No | "Peec Actions" recommendations, no publishing | Geo-priced, roughly $95/mo equivalent |
| Otterly.AI | ChatGPT, Perplexity, AI Overviews | No | No | $29/mo |
| Rankscale | 17+ engines claimed | No | AI Readiness Score audit checklist | ~€20/mo |
Worth being blunt about the split here: most of this category answers "was my brand mentioned?" and stops there. That's useful for reporting, but it leaves the actual fixing to you. Promptwatch is built around the full loop instead: crawler logs explain why you're or aren't visible, citation analytics (including dedicated Reddit and YouTube reports most competitors skip entirely) show where AI finds your content, visitor analytics tie it to actual traffic and conversions, and Content Agents plan, write, and publish GEO-optimized content to your CMS on a schedule, with Unified Actions turning all of it into a prioritized to-do list rather than a dashboard nobody opens twice.
For budget-conscious teams just starting out, Otterly.AI or the free-tier options are a reasonable entry point.
Otterly.AI

Agencies managing several clients might look at Profound's enterprise tier or Peec AI's localization features.
Profound
If you want to see the full field of options laid out side by side, including newer entrants not covered here, the GEO software directory at bestgeosoftware.com tracks the category on an ongoing basis, and agenticseotools.com is worth a look if you specifically want tools that act on findings rather than just report them.
Building the routing that makes monitoring worth doing
A weekly AI-visibility report that lands in nobody's inbox is worse than no report at all, because it creates the illusion that you're on top of it. The teams getting real value from this route findings into three places: content (which gaps need new pages or updated ones), technical SEO (crawlability, structured data, whether your site handles the site: searches ChatGPT is now running), and leadership (share of voice trend, because that's the number that gets budget approved).
If your team is stretched thin and this is genuinely new territory, it's also the kind of work an outside team can stand up quickly. 1001 SEO Media builds exactly this kind of AI-search monitoring and content program for clients who need the framework running without hiring an in-house team from scratch, combining technical audits with the content production to actually close the gaps once they're found.
Where to start this week
Don't try to build the perfect 200-prompt tracking matrix on day one. Pick your top 15-20 prompts, split roughly 70/30 between category queries and branded ones, run them across ChatGPT, Perplexity, Gemini, and Google's AI surfaces, and log presence, citation, and sentiment for each. Repeat weekly for a month before drawing conclusions about trend direction. That's a small enough scope to actually maintain, and it will tell you more in four weeks than a one-time audit ever could.